


Credible beats correct
Where answers can’t be verified, show where each claim came from and how it was reached, not certainty.
Helping execs see what matters, and check why
Zero Gaps was an experimental AI insights tool for the execs who run and govern employee experiences: a desktop web dashboard with a conversational agent built in.
It tracked where internal teams were blocked by limits in the products they relied on, so execs could raise the right issues with the teams that owned them.
I owned the front-end experience and helped shape the story the data could honestly tell, alongside five PMs and one engineer, over three months.
The real Zero Gaps work is under NDA,
so I’ve retold the visuals in this case study through a different persona.
She’s a city council member.
Like the execs at Microsoft, she makes sure residents’ requests are heard.
She unblocks work by understanding why it’s stuck, then bringing it to the department that can make it a priority.
Leslie
City Council
Member
The reality
An official report took weeks and several layers of people to collect and organize, and with no one place to check, execs pinged their teams for updates before every product meeting.
The ask
The brief asked AI to score every issue by business impact, so execs could prepare in three minutes. The signal existed, but it was scattered across work items, meetings and files, and every team tracked it differently.
The strategy
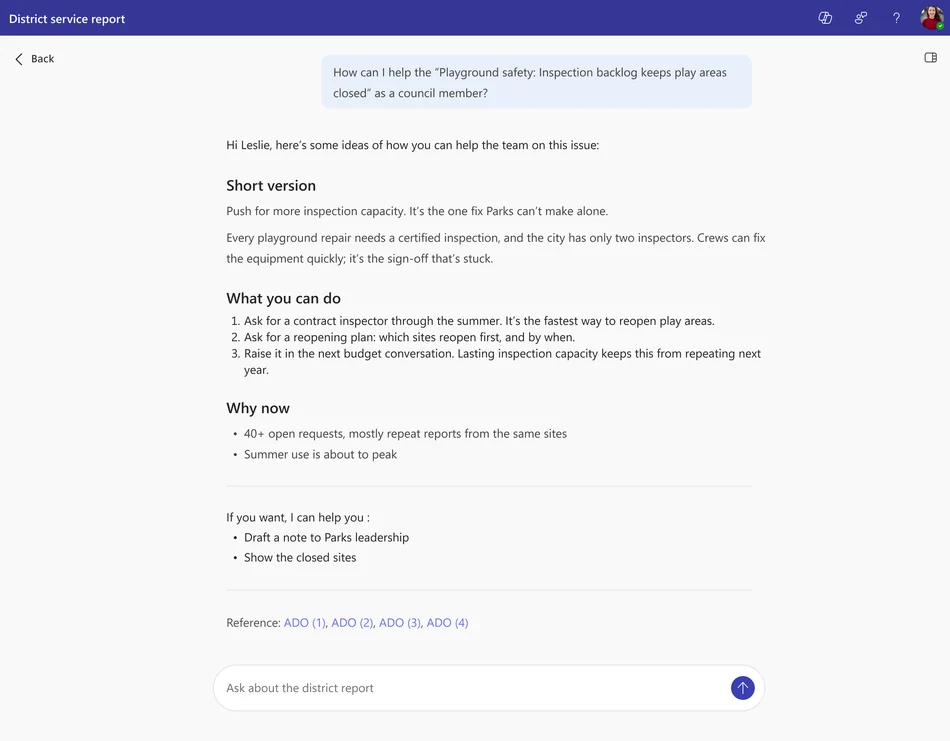
The early push was for a conversational agent experience.
I argued that a blank prompt makes busy execs do the work, so we paired a scannable dashboard with an agent for follow-up questions.
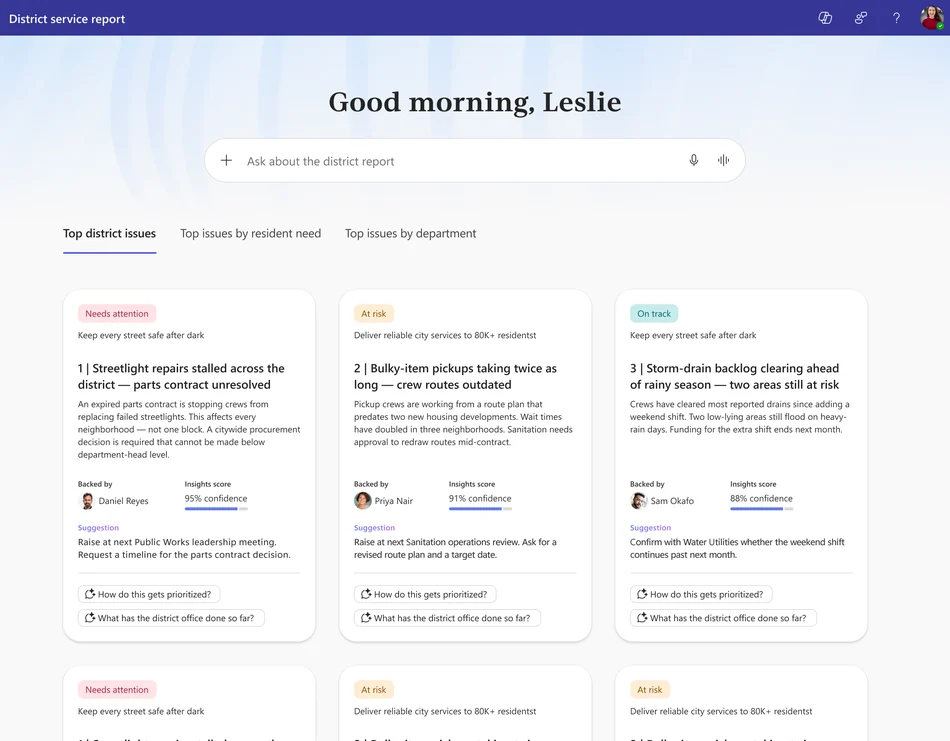
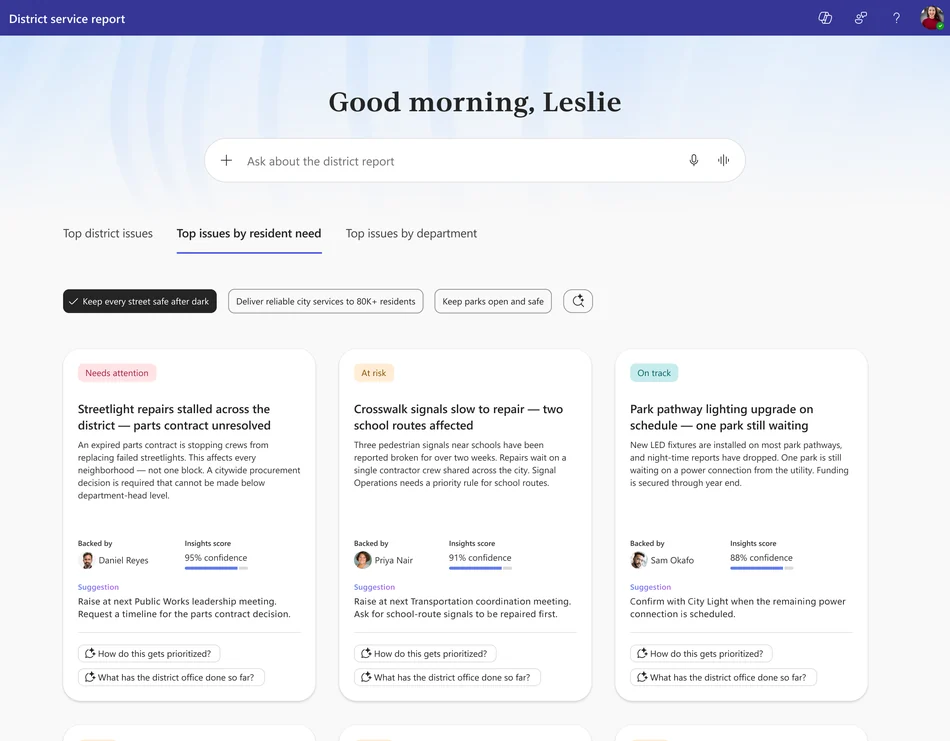
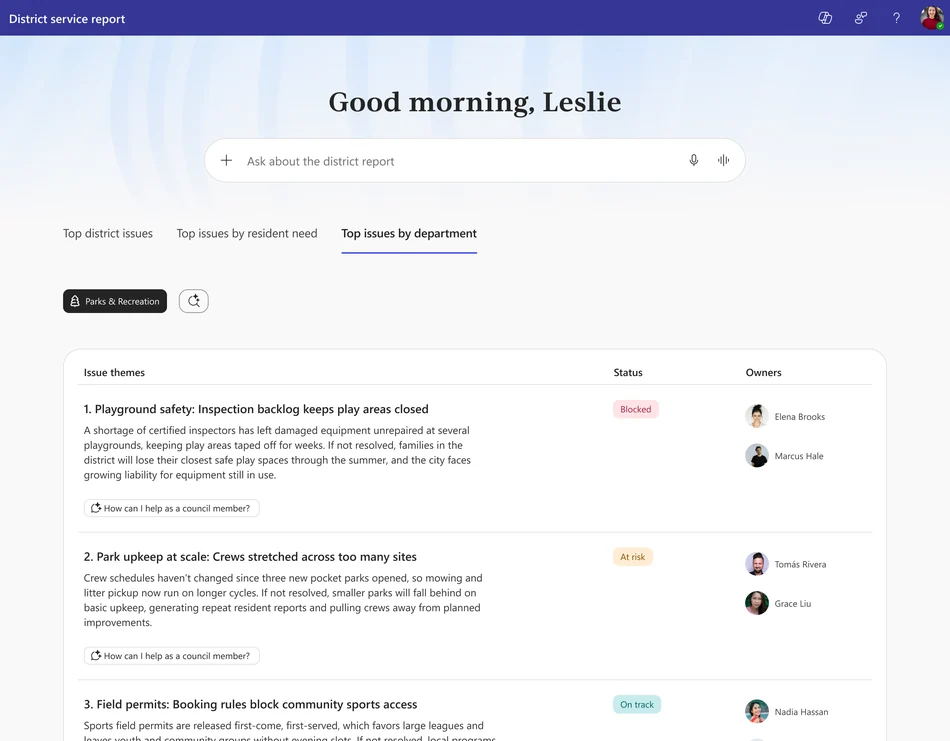


The feedback
Product leaders pushed back on the scores, and they were right to. Some were wrong because of stale data. Others couldn’t be proven. The tool claimed more certainty than it could back.
The pivot
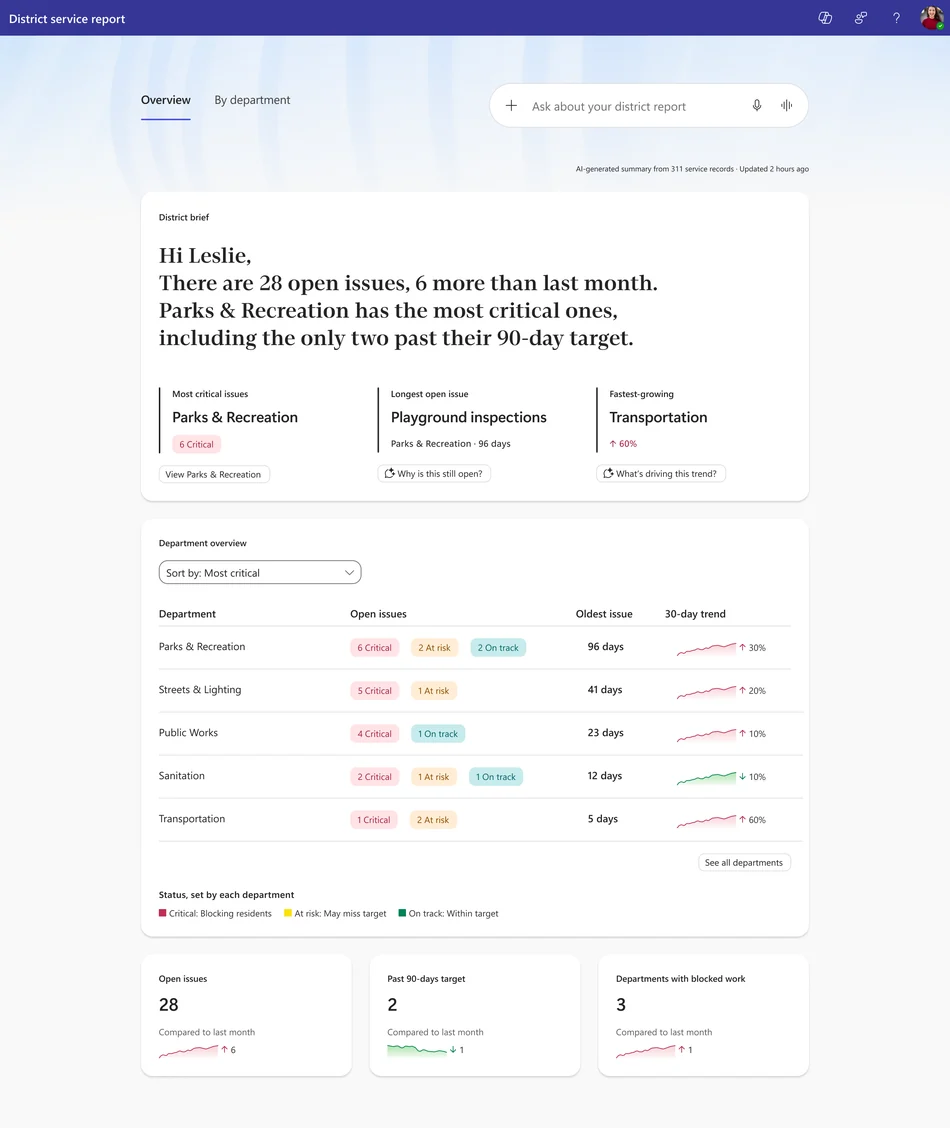
After the pushback, the team agreed to stop scoring and show only what the data could back, and I turned that into the v2 concept. The question shifted from “Is this right?” to “Is this useful?” A lead doesn’t have to be right. It has to hold up when someone checks it.
One place to look, updated hours ago, not weeks.
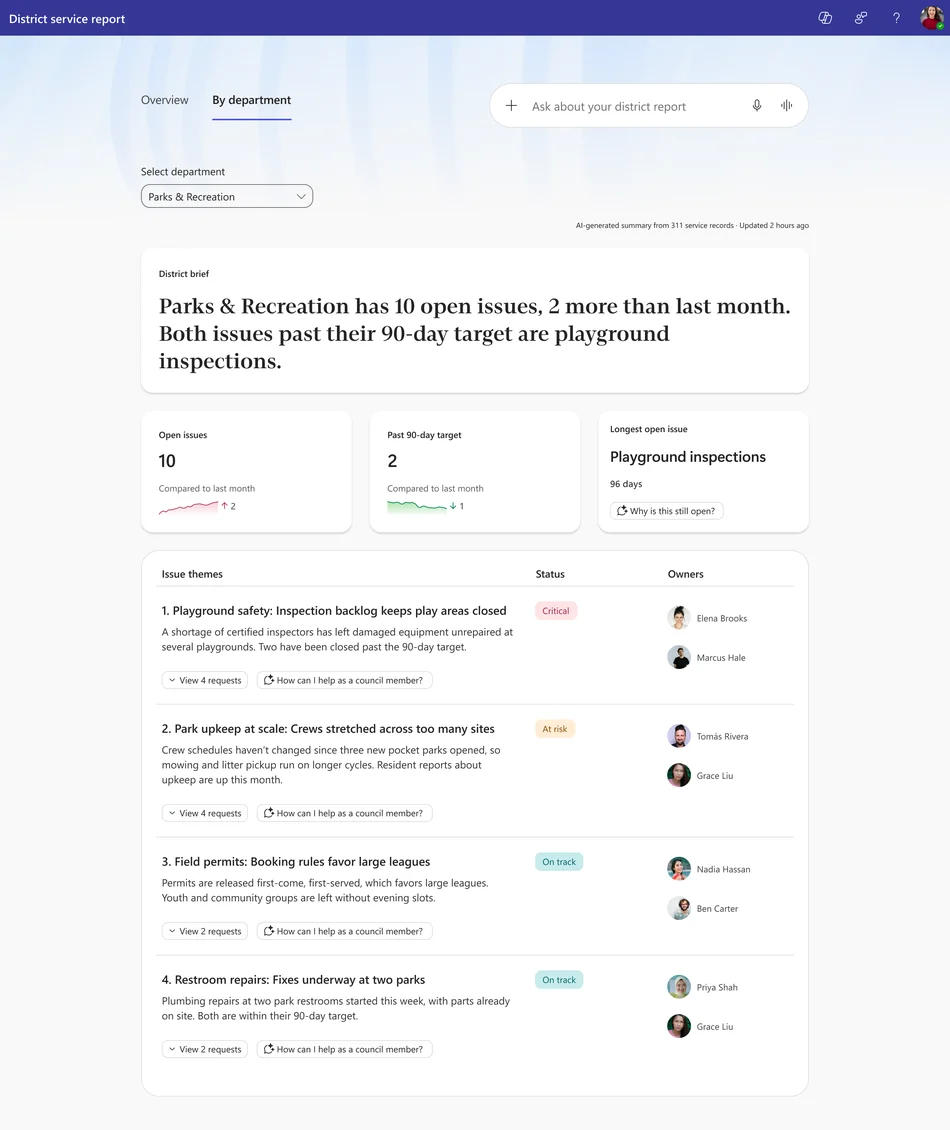
V2 earned the lead PM’s support and was heading to leadership review when I left Microsoft. The project’s ending isn’t mine to tell, but the principles came with me.
Where answers can’t be verified, show where each claim came from and how it was reached, not certainty.
Scope AI to what the data supports today, and widen it as both mature.
An AI that ranks people’s work has to make sense to those people, not just to the person reading it.